Peer ranked precision, measured.
The DataSeeds Sample Dataset (DSD) shows how peer ranked, human annotated photography outperforms common datasets and tagging APIs on precision tasks: technical scene understanding and aesthetic modeling.
The bottleneck is no longer compute. It is data.
7,843
high resolution, rights cleared photographs, each peer ranked by the GuruShots community and annotated by expert reviewers.
24.09%
relative BLEU-4 gain for LLaVA-NeXT after fine tuning on the DSD, with ROUGE-L, BERTScore and CLIPScore rising alongside.
0.19 F1
is all AWS Rekognition scored against the DSD annotations: the ceiling of automated commercial tagging on high quality curation.
The experiment
Two vision language models, one fine tune on the DSD
Two state of the art vision language models were fine tuned on the DataSeeds Sample Dataset, drawn from GuruShots' catalog. Both showed consistent, measurable improvements across the caption metrics, and both began to identify small but semantically significant details (a bee's legs in flight, handwritten text on a chalkboard) that off the shelf commercial APIs skip.
| Model | BLEU-4 | ROUGE-L | BERTScore F1 | CLIPScore |
|---|---|---|---|---|
| LLaVA-NeXT (base) | 0.0199 | 0.2089 | 0.2751 | 0.3247 |
| LLaVA-NeXT (fine tuned on DSD) | 0.0246 | 0.2140 | 0.2789 | 0.3260 |
| Absolute improvement | +0.0048 | +0.0051 | +0.0039 | +0.0013 |
| Relative improvement | +24.09% | +2.44% | +1.40% | +0.41% |
| Model | BLEU-4 | ROUGE-L | BERTScore F1 | CLIPScore |
|---|---|---|---|---|
| BLIP2 (base) | 0.001 | 0.126 | 0.0545 | 0.2854 |
| BLIP2 (fine tuned on DSD) | 0.047 | 0.242 | -0.0537 | 0.2583 |
| Absolute improvement | +0.046 | +0.116 | -0.1082 | -0.0271 |
| Relative improvement | +4600.00% | +92.06% | -198.53% | -9.49% |
BLIP2 gains fluency (BLEU-4, ROUGE-L) while its embedding based scores drop, a known tradeoff when a small model learns a richer caption style. Full protocol, splits and seeds are in the paper and the repository.
What the models learned
Not just what is in the image, but how and why it matters
The DSD pairs high resolution photography with layered human annotation: object relationships, compositional descriptors, and technical photography metadata. Trained on it, models internalize scene level nuance that generic corpora lose, and they read text embedded in the image itself far more reliably.
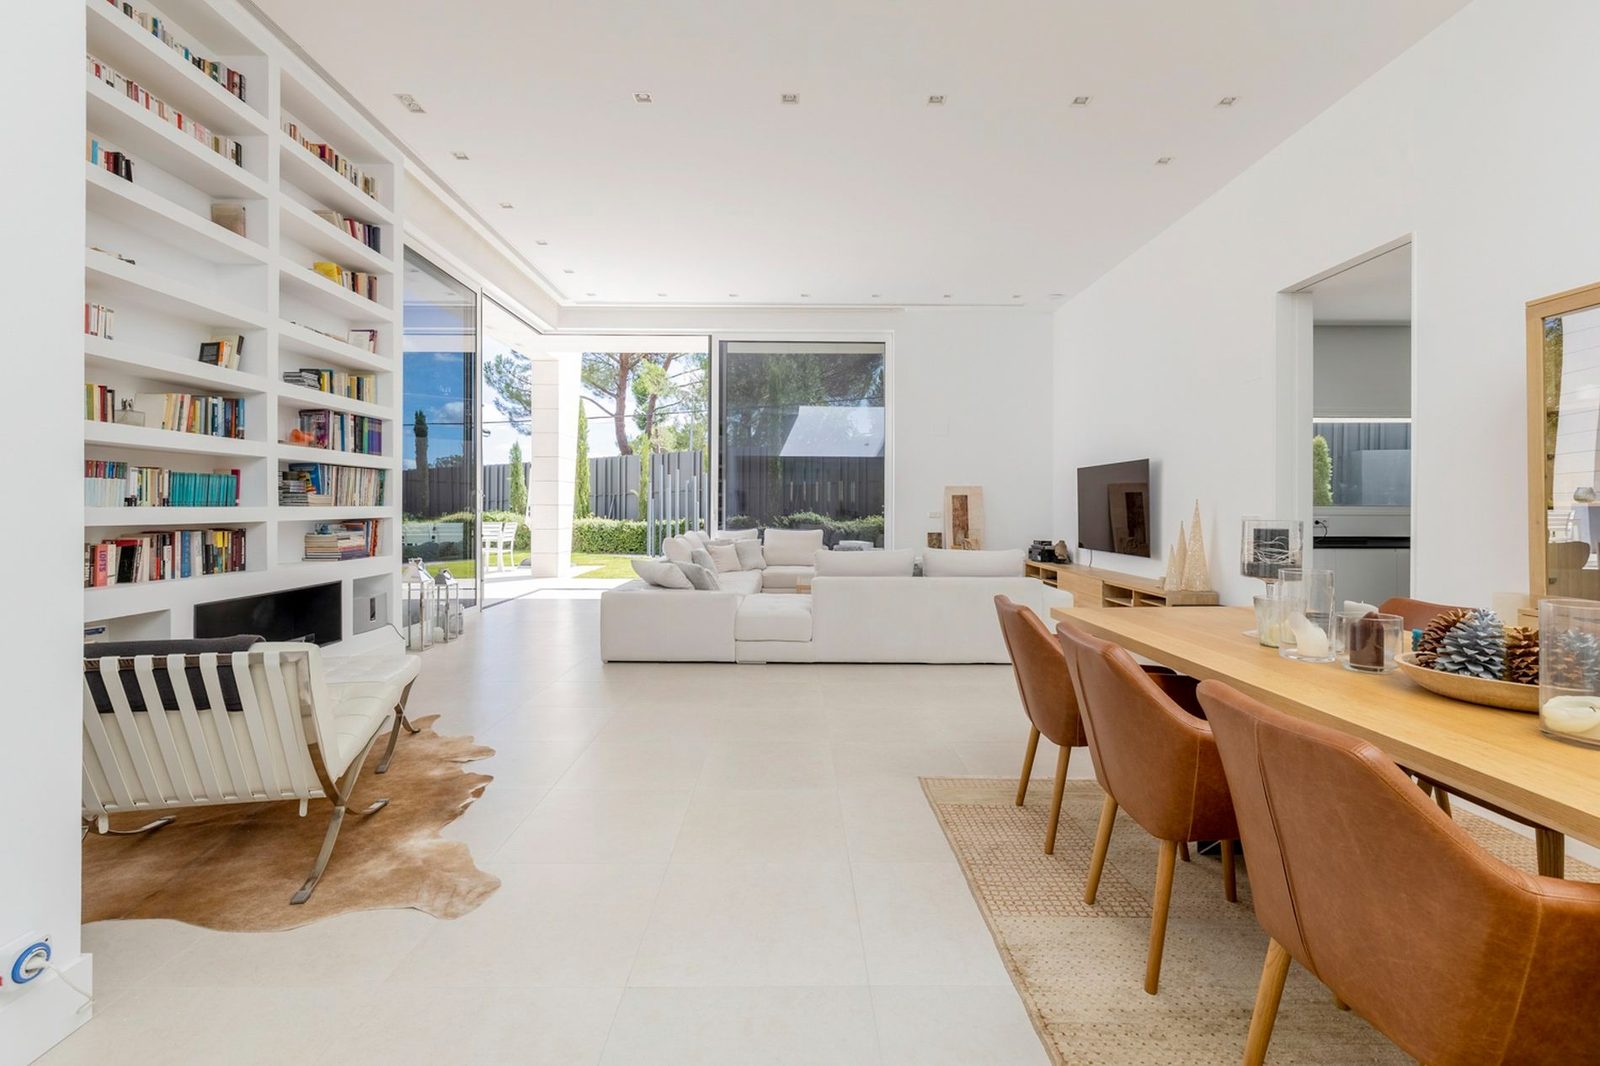
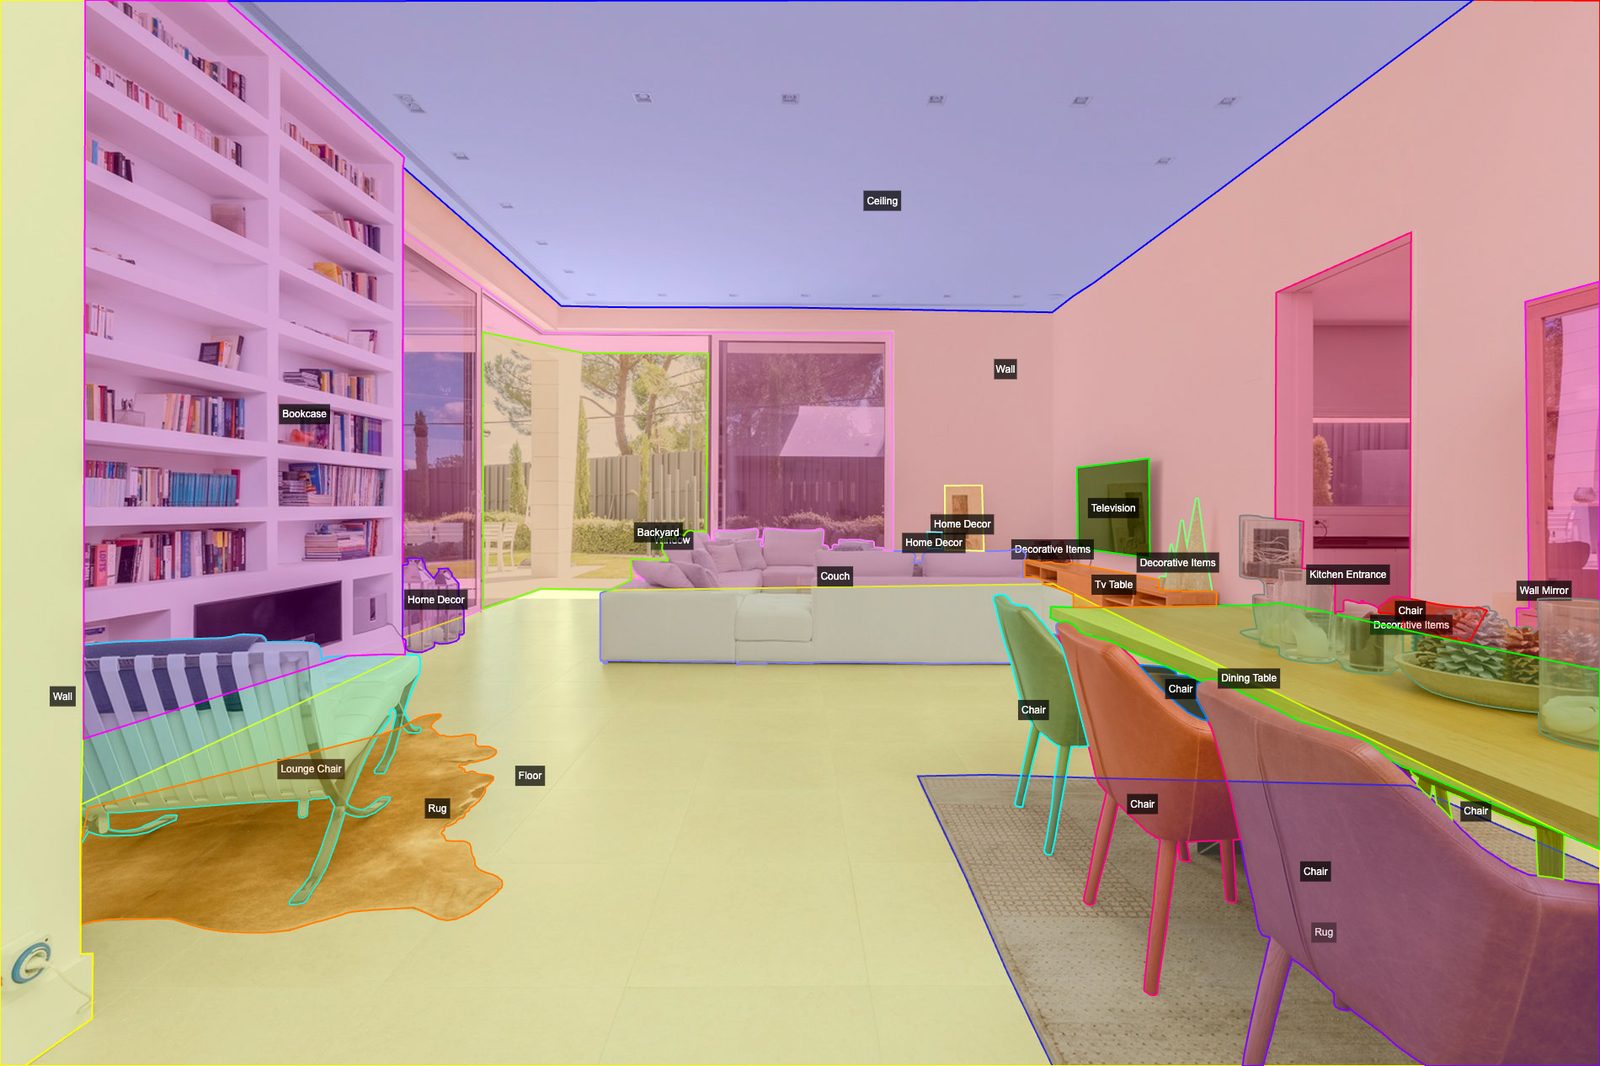
To our knowledge, the DSD is the first dataset to combine photographic peer ranking, structured human in the loop annotation, and pixel level segmentation for evaluating and fine tuning vision language models at scale.
The result validates a core thesis of our work: when models see high quality, human ranked visual data at scale, they learn to prioritize the same subtle cues human observers do: stronger alignment, better semantic grounding, more reliable outputs in deployment.
Commercial access
The DSD is the public sample. The catalog and the crowd are the product.
Beyond the 50M+ image catalog, DataSeeds.AI sources new image, video, and audio datasets to spec through a just in time, first party acquisition engine. Within days a curated mission reaches the 20M+ monthly contributor network and returns a targeted set under commercial grade licensing, with optional human in the loop annotation.
Content themes
Urban decay at dusk. Elderly people with dogs in snow. Kosher food. Anything a brief can describe.
Technical attributes
Camera type, exposure, focal length, geographic constraints, resolution floors.
Ethical filtering
GDPR compliant imagery, no identifiable faces, region specific consent rules.
Delivered with
Segmentation masks, EXIF metadata, tiered annotations, rights documentation.